
SCIENCE IS AT THE CORE OF MAVENMAGNET
PLATFORM AND PRODUCTS
From data collection to advanced analysis to insight generation, rigorous science and cutting‑edge technology power every step of our process. Our proprietary technology platform enables us to extract verbatims at scale, analyze multimodal data with precision, and deliver actionable insights — all while maintaining strict GDPR and privacy compliance.

Fine‑tuned, purpose‑built foundational models for each category and sub‑segment form the core of our analytical architecture. These models operate through intelligent agents that orchestrate data ingestion, signal extraction, pattern recognition, and insight synthesis across a unified digital landscape. Each agent is designed to understand the structural nuances of its domain, including taxonomy, behavioral markers, contextual cues, and multimodal content formats. This allows the system to interpret consumer behavior with high fidelity and maintain consistency across diverse data sources.
Our platform applies transfer learning from best‑in‑class base models and adapts them to the specific linguistic, behavioral, and contextual characteristics of each industry. This adaptation process enables us to deliver custom, domain‑specific solutions that address complex customer challenges and support critical business decisions. The agents leverage hierarchical embeddings, semantic clustering, and cross‑modal alignment techniques to ensure that insights remain accurate, scalable, and contextually grounded.
We follow a continuous cyclic training process that strengthens the entire system over time. Trustworthy data feeds the initial learning layer, multi‑level analysis refines the signal, and insight extraction provides the interpretive framework. Customer feedback then informs the next iteration of model tuning. This cycle enhances precision, reduces noise, and improves the efficiency of both the foundational models and the agents that operate on top of them. As the system evolves, agents become more context‑aware, more adaptive to emerging patterns, and more capable of delivering actionable intelligence at enterprise scale.
Digital Mapping™ is a proprietary MavenMagnet technique designed to perform noise‑free, bias‑free, and high‑relevance data aggregation from third‑party digital platforms. Instead of relying on keyword searches, which often introduce bias, miss contextual signals, and require awkward Boolean pairing, Digital Mapping constructs a domain‑specific map aligned to the business objectives of the analysis. This map guides the aggregation of data from diverse digital sources including blogs, forums, news articles, consumer reviews, video logs, audio files, and social networks.
The technique incorporates contextual understanding models that evaluate the semantic structure of conversations and determine whether content is relevant to the defined business objectives. This eliminates the dependency on keyword matching and significantly reduces the inclusion of irrelevant or misleading data. Digital Mapping is grounded in statistical fundamentals that filter out noise, remove low‑value content, and organize high‑context information into structured datasets ready for downstream analysis.
Before the clean‑up process is applied, the average precision of the aggregated data is approximately 0.20. Because Digital Mapping does not rely on keyword search, typical recall is 40 to 45 percent higher than conventional search engines and social media monitoring tools. This elevated recall is a direct result of the contextual aggregation process, which captures a broader and more accurate representation of relevant conversations.
A key element of Digital Mapping is the noise elimination module. This module applies statistical relevance scoring, contextual validation, and multi‑layer filtering to remove non‑contextual and low‑value data. After this clean‑up process, precision increases to approximately 0.95 while maintaining the high recall achieved during aggregation. This combination of high precision and high recall produces a dataset that is both comprehensive and highly accurate, enabling deeper and more reliable insight generation across categories and markets.


Discovery is a core methodological principle within the MavenMagnet ecosystem. It ensures that insight generation is driven entirely by naturally occurring consumer behavior rather than preconceived assumptions or artificial research constructs. The objective is to eliminate structural bias, expand the observable universe of data, and produce a complete, unprompted understanding of the market landscape.
Discovery operates without preconceived notions. Instead, the system captures real conversations as they unfold across the unified digital landscape, allowing consumer narratives to emerge organically and without intervention.
This process is powered by omni‑source intelligence platforms that aggregate and analyze data from a wide spectrum of digital environments. The platform seamlessly integrates first‑party and second‑party data with extensive third‑party sources, including millions of forums, message boards, review sites, chat rooms, social platforms, video logs, audio files, and news ecosystems. Advanced cognitive intent signals further enhance relevance and contextual accuracy, enabling the system to surface precise and actionable insights.
By relying exclusively on naturally occurring content rather than prompted responses, Discovery produces a more authentic and comprehensive representation of consumer sentiment, behavioral patterns, and thematic structures. The analytical pipeline applies advanced contextual modeling, multi‑level semantic analysis, and domain‑specific large language models to interpret these conversations with high fidelity.
Insights are generated from complete discovery rather than guided inquiry, ensuring that themes, sentiments, and behavioral signals reflect the true voice of the consumer. This approach removes the limitations inherent in traditional research instruments and enables a deeper, more accurate, and more scalable understanding of market dynamics.
Segmented data aggregation enables precise listening to highly specific target audiences and supports more informed business decision‑making. The process begins with micro‑segment identification. These micro‑segments allow the analytical engine to focus on the exact audience relevant to the business objective, improving both the precision and contextual relevance of insights.
Our platform uses MavenMagnet’s proprietary Consumer Mapping™ technique to construct a detailed demographic profile of each micro‑segment. Consumer Mapping incorporates statistical modeling, linguistic orientation analysis, and geo‑contextual tagging to determine who the consumers are, where they are located, and how they communicate across digital environments.
To deepen the segmentation, Consumer Mapping is combined with MavenMagnet Correlation Mechanics. This component applies behavioral correlation analysis, psychographic inference models, and contextual signal mapping to determine the underlying motivations, attitudes, and lifestyle indicators of the target consumers. The integration of demographic, geographic, linguistic, and psychographic layers produces a multi‑dimensional view of each micro‑segment.
This technically robust approach ensures that segmented data aggregation is not limited to surface‑level attributes. Instead, it delivers a high‑resolution understanding of the target audience, enabling more accurate insight generation and more effective tactical and strategic decision‑making.
Theme Identification Engine™ isolates the core conversational themes that shape consumer narratives. It uses fine‑tuned large language models trained on domain‑specific corpora to detect, classify, and prioritize thematic structures with high accuracy. These models operate within our Insights Mining Framework, which applies layered semantic analysis, contextual reasoning, and relevance scoring to extract insights that are both granular and actionable.
Each model is engineered at the category‑cluster level, allowing it to capture the linguistic patterns, behavioral cues, and contextual nuances unique to that category. This design produces more precise theme detection, richer sub‑theme differentiation, and deeper interpretive fidelity across diverse digital conversations. The result is a technically robust system that transforms unstructured data into structured intelligence with significantly higher resolution and reliability.
Insights Mining Framework™ is a core MavenMagnet technology that establishes the analytical structure required for multi‑level deep‑dive analysis and high‑resolution insight extraction across unlimited datasets. It works in tandem with the Theme Identification Engine, which isolates and prioritizes the core conversational themes that shape consumer narratives. Once the Theme Identification Engine identifies the thematic architecture of the data, the Insights Mining Framework applies layered semantic processing, contextual reasoning, and structured interpretation to convert those themes into actionable intelligence.
The framework uses fine‑tuned large language models that are extensively trained across category clusters and sub‑segments. These models incorporate domain‑specific taxonomies, linguistic patterns, and behavioral cues, allowing them to operate with high fidelity in complex digital environments. Because each model is adapted to the structural nuances of its category, the system produces more accurate theme detection, richer sub‑theme differentiation, and deeper insight extraction.
The Insights Mining Framework is fully operational across more than 100 categories in over 25 global markets. Its architecture supports scalable ingestion, cross‑market adaptation, and consistent interpretive quality, enabling enterprises to analyze massive volumes of unstructured data with precision and reliability.
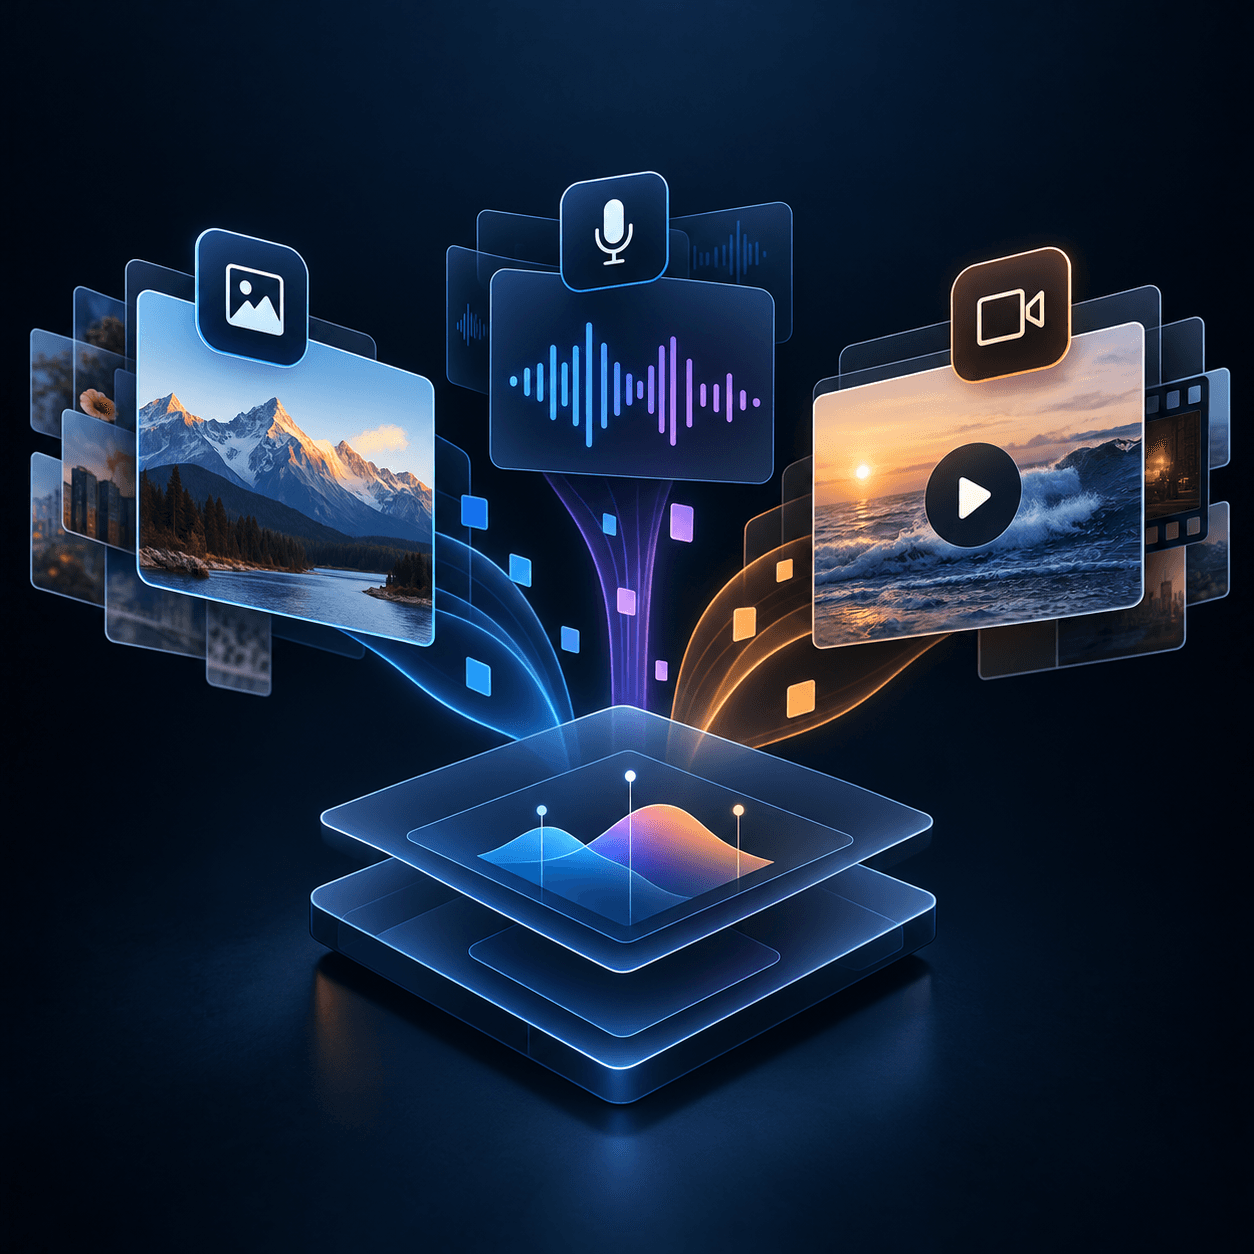
Image, audio, and video analysis form a critical component of our technology infrastructure and allow us to generate comprehensive insights from the unified digital landscape. Through fine‑tuning and advanced prompt engineering applied to large language models, we have built strong capabilities for interpreting and analyzing data across multiple formats.
Our multimodal stack includes specialized models for Speech‑to‑Text, Speech Emotion Recognition, Speech Segmentation, and image understanding. These models are trained on diverse, domain‑aligned datasets to ensure high accuracy in real‑world environments. The Speech‑to‑Text models convert audio calls into structured transcripts, the emotion recognition models identify tonal and affective cues, and the segmentation models isolate speakers and contextual segments within conversations. Our image analysis models detect objects, classify scenes, and interpret visual cues with high fidelity.
Together, these components enable us to analyze audio calls, images, and videos with precision and consistency. This multimodal capability integrates seamlessly with the Theme Identification Engine and the Insights Mining Framework, allowing us to extract richer, more holistic insights from the full spectrum of digital content.
MavenMagnet Predictive Modeling identifies structural patterns in historical datasets and converts them into leading indicators that anticipate future outcomes. The system pairs these forward‑looking signals with a detailed action plan that includes both tactical and strategic recommendations aligned to the client’s business objectives.
Our predictive capability is built on advanced data aggregation pipelines, machine learning algorithms, and custom predictive analytics models. These components work together to normalize heterogeneous data sources, detect temporal and behavioral trends, and generate probabilistic forecasts with high reliability. The modeling stack incorporates supervised learning, feature engineering, and scenario simulation to ensure that predictions remain robust across varying market conditions.
By integrating these techniques, MavenMagnet Predictive Modeling transforms raw historical data into decision‑ready intelligence that drives actionability and supports high‑stakes planning across categories and markets.

Vibe Sensor™ identifies the sentiment and emotional tone associated with each theme uncovered by the Theme Identification Engine. It is a specialized technique that ensures the correct sentiments are mapped to the correct thematic segments within a conversation. This alignment is essential for producing high‑fidelity insight, since sentiment often shifts across topics, speakers, and contextual cues.
Our sentiment analysis pipeline processes text data and assigns both polarity and emotional state to each theme. The system uses prompt‑trained foundational models that have been fine‑tuned for granular sentiment and emotion classification. These models incorporate domain‑specific lexicons, contextual embeddings, and multi‑label classification strategies that allow them to detect subtle affective signals.
The Vibe Sensor is engineered to handle complex linguistic phenomena such as slang, sarcasm, technical terminology, implicit sentiment, and mixed emotional states within the same conversational segment. It evaluates tone at multiple levels, including lexical, semantic, and contextual layers, and applies consistency checks to ensure accurate sentiment‑theme association.
By combining advanced LLM fine‑tuning with robust sentiment modeling techniques, the Vibe Sensor produces a precise emotional map of consumer conversations. This emotional mapping integrates seamlessly with the Insights Mining Framework and Theme Identification Engine, enabling a deeper and more reliable interpretation of consumer behavior across the unified digital landscape.

Turn your data into decisions that move your business forward.
Discover what MavenMagnet can unlock for your organization.

Turn your data into decisions that move your business forward.
Discover what MavenMagnet can unlock for your organization.
